Delfos Telematics: Fleet Visibility and Control Guide
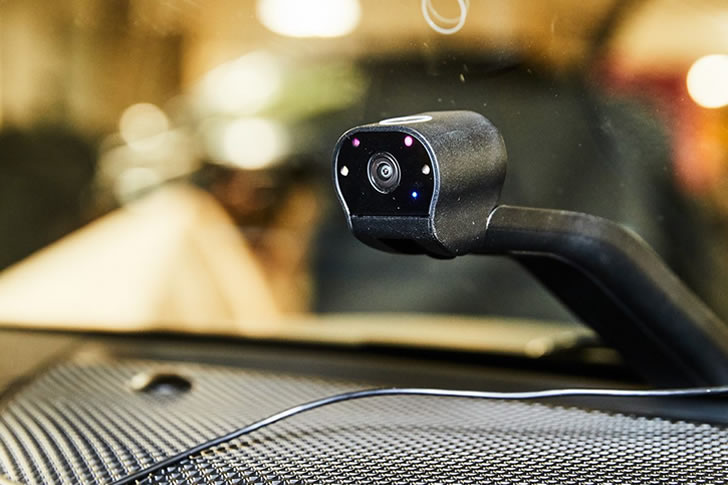
This guide explains how Delfos Telematics supports fleet visibility, driver behavior monitoring, and operational control through data-driven workflows. Delfos Telematics is typically deployed to connect vehicles and assets to a central platform, enabling organizations to collect location, movement, and performance signals. The article provides objective context on deployment, governance, and practical requirements.
1) Executive overview: what Delfos Telematics helps you achieve
Delfos Telematics is designed to strengthen fleet visibility and improve operational control by connecting vehicles and assets to an information platform where location, movement, and usage signals can be analyzed. For fleet operators, the very tangible value usually appears when data is turned into decisions: smarter routing, better maintenance planning, and clearer oversight of how vehicles are being used day to day. Instead of relying solely on manual reporting or sporadic check-ins, a telematics approach supports consistent monitoring and faster issue detection.
What makes a telematics platform “helpful” in practice is not the raw fact that vehicles can be located on a map—it’s the operational transformation that comes from interpreting signals correctly and consistently. When Delfos Telematics is configured and governed properly, it can help you build an evidence-based operating model: dispatchers can validate whether a vehicle is where it should be; maintenance planners can see patterns that correlate with component wear; and safety managers can use behavioral or operational indicators to support coaching and process improvement.
From an industry-expert perspective, it’s important to treat telematics as a governance system as much as an analytics system. Vehicle data becomes useful when it is standardized, permissioned, and translated into repeatable processes—such as alert handling, maintenance workflows, and exception management—rather than simply stored for later viewing. In other words, the “platform” is only one half of the solution; the other half is operational discipline: who reviews the information, what decisions are taken, how exceptions are investigated, and how learnings are fed back into planning and training.
When you implement Delfos Telematics with that mindset, you typically see improvements across several operational dimensions:
- Visibility: real-time or near-real-time location awareness and activity history.
- Control: ability to detect deviations from planned work patterns and quickly investigate root causes.
- Responsiveness: earlier detection of incidents, anomalies, and emerging maintenance needs.
- Accountability: traceability of events and documented workflows for audits and internal governance.
- Continuous improvement: trend analysis that informs better scheduling, training, and asset management.
Ultimately, telematics helps you move from a reactive model—where problems are noticed after they cause delays—toward a proactive model, where you see leading indicators and can intervene earlier. That shift tends to be the difference between “having a system” and “running an operational advantage.”
2) Why telematics remains strategically relevant for fleets
Telematics has grown because fleets face a predictable combination of pressures: operational cost constraints, rising expectations for service reliability, and greater scrutiny around safety and compliance. In many regions, customers and regulators increasingly expect documented performance, reliable delivery/servicing, and evidence that safety processes are actively managed—not just described.
Internationally, the direction of travel in fleet operations is toward measurable outcomes—reduced downtime, improved asset utilization, and documented safety practices—supported by traceable data trails. As budgets tighten, fleets cannot afford to treat telemetry as a “nice-to-have” experiment. They need evidence that operational decisions are improving outcomes and that risk is being managed with data-informed governance.
In this context, Delfos Telematics is best understood as a tool that links field activity to centralized visibility. Many organizations seek telematics to answer questions such as: Where are vehicles at any given time? Are there deviations from planned work patterns? Which assets show early signs of increased wear? How do driving patterns correlate with incident risk or avoidable inefficiencies? While the exact feature set depends on the deployment configuration, the operational intent usually follows this measurable decision chain.
To make telematics strategically relevant, fleets typically focus on three levels of value:
- Operational level: reduce delays, improve routing, speed up dispatch decisions, and coordinate field work effectively.
- Asset management level: shift from calendar-based maintenance toward condition-informed maintenance, where feasible.
- Governance and risk level: demonstrate compliance readiness, manage safety processes, and maintain traceability for investigations.
Another reason telematics remains relevant is that the technology becomes more valuable as operations scale. When you run a larger number of assets, manual oversight becomes harder, and the cost of lost time or missed maintenance increases. Telemetry offers a way to standardize oversight across multiple depots, routes, or job types—supporting consistent processes regardless of local variability.
Finally, telematics aligns with broader digital transformation trends: as fleets modernize dispatch systems, integrate enterprise reporting, and adopt standardized operating procedures, telematics becomes a foundational data source that can power those initiatives rather than remaining an isolated system.
3) Core capabilities commonly associated with Delfos Telematics
Although deployments can vary, telematics solutions in the Delfos Telematics category are typically used to capture three broad categories of signals:
- Location and movement signals: enabling route awareness, geofencing logic, and activity history.
- Usage and operational signals: supporting insights into how assets are utilized and when they are active.
- Performance and driving-related indicators: used to understand operating conditions and identify patterns that may require coaching or maintenance attention.
An expert way to think about these capabilities is as “input data” that can be converted into “operational actions.” For example, if an organization identifies frequent stop-start patterns on certain routes, it can investigate whether route planning, scheduling, vehicle assignment, or driver habits are contributing factors—then document the corrective steps taken.
To build this transformation properly, fleets should understand what each signal family can realistically support:
Location and movement signals are often used to:
- confirm arrival and departure times at service points (helpful for both customer experience and internal billing processes where applicable);
- monitor route adherence for safety and efficiency;
- identify out-of-zone activity that may indicate misrouting, unauthorized movement, or exceptional circumstances requiring escalation;
- provide activity timelines that can support incident investigations or audits.
Usage and operational signals are often used to:
- measure how intensively an asset is used (e.g., utilization rate, active hours);
- identify underutilized assets that may need reassignment or different scheduling;
- detect operational anomalies such as unexpected idle times, frequent short trips, or activity outside expected windows;
- support job planning improvements by observing how work truly happens versus how it is planned.
Performance and driving-related indicators are often used to:
- flag risky driving behaviors for coaching and safety training;
- create patterns that correlate with maintenance needs (e.g., harsh driving events that accelerate component wear);
- improve driver education by providing objective evidence, when governance and communication are handled properly;
- reduce claim frequency or severity by identifying leading indicators and addressing them early.
It’s worth emphasizing that these capabilities are most valuable when they are not treated as independent features. The strongest operational results usually come from linking signals into workflows. For instance: if location shows consistent deviations and driving indicators show harsh events, the fleet can choose a combined response—such as adjusting route planning and offering driver coaching—while documenting the intervention and measuring whether the deviation frequency decreases over time.
In addition, many fleets benefit from building a “single version of operational truth” by standardizing how signals are recorded and interpreted across teams. When dispatch, maintenance, and safety teams use the same underlying signals, collaboration improves and decision-making becomes less subjective.
4) Pricing considerations: what you should expect when evaluating Delfos Telematics
When customers ask about Delfos Telematics pricing, the very important point is that pricing is rarely one single number in real-world procurement. Costs typically depend on factors such as the number of vehicles/assets, the type of device configuration, installation requirements, contract term, data retention policies, and the scope of platform modules enabled.
Because you did not provide specific supplier quotations or a fixed price point, the responsible approach is to frame pricing as a procurement range influenced by scale and scope. To evaluate options fairly, request a written quotation that breaks down costs clearly. A well-structured quotation helps you compare like-for-like across suppliers and avoids the common situation where a “low initial cost” turns into high lifecycle cost after add-ons are included.
When preparing for discussions with suppliers or partners, request a written quotation that breaks down:
- per-unit device or integration costs (if applicable), including any hardware variants and their implications;
- monthly or annual platform fees per vehicle/asset, and what exactly is included in the subscription tier;
- installation and onboarding support, including whether it includes kitting, mounting, configuration, and user training;
- any optional analytics modules or user licenses, such as advanced reporting, safety scoring, or maintenance decision aids;
- ongoing support, maintenance, and service-level terms, including response times, escalation paths, and support availability windows.
This structure helps you compare like-for-like across suppliers and ensures you can plan budgeting accurately for near-term deployment and longer-term operations.
Beyond the headline pricing components, fleets often overlook other cost drivers that matter for total cost of ownership. Consider asking about:
- Device lifecycle and replacement costs: how replacements are handled when a device fails or a vehicle changes ownership;
- Data export and reporting costs: whether exports are included or if there are usage-based limits;
- Custom dashboard or report development: whether custom work is included or billed separately;
- Integration costs: whether integration with maintenance systems, dispatch tools, or data warehouses is part of the base offer;
- Training and change management: whether the supplier offers adoption support or if internal teams must design the training materials.
A useful procurement technique is to estimate your “deployment phases,” such as pilot, rollout to the full fleet, and later expansion of modules. Many contracts price differently depending on the phase and contract duration. If you expect to expand, you can ask for pricing logic that remains predictable as you scale.
Finally, do not evaluate pricing in isolation from operational fit. A slightly higher price can be justified if the platform reduces the labor burden of reporting, improves alert accuracy, or shortens time-to-resolution during incidents. The best approach is to link pricing decisions to the operational outcomes you want to measure during the pilot.
5) Supplier and deployment realities (and why they matter)
In practice, Delfos Telematics implementations are influenced by supplier responsibilities and integration boundaries. A supplier may handle device provisioning, installation coordination, configuration of dashboards, training, and system administration. Alternatively, some organizations run internal responsibilities for user provisioning, data governance, and operational workflows. The key is to define what “good handover” means so the project does not stall at go-live.
Common areas where implementation teams should align early include:
- Access control: who can view data, export reports, or configure alerts.
- Data accuracy expectations: what “location correctness” means operationally and how it will be verified.
- Integration scope: whether telematics data must connect with maintenance systems, dispatch tools, or enterprise reporting.
- Operational process ownership: who reviews exceptions and what happens when an alert triggers.
From an objective standpoint, those choices determine whether the platform becomes an operational advantage—or a dashboard that nobody fully uses. Fleets often invest in devices and software, but under-invest in process design. When process ownership is unclear, alerts arrive without an action pathway, and staff eventually ignore signals due to frustration or uncertainty.
To avoid this outcome, many successful deployments apply a RACI-style approach (Responsible, Accountable, Consulted, Informed) or a similar decision model. For each workflow—such as “geofence breach review,” “maintenance trigger validation,” or “driving incident investigation”—you should clarify:
- who owns the decision to act;
- who investigates the cause;
- who is consulted for technical interpretation;
- who must be informed for governance or customer communications.
Another deployment reality is variability in vehicle types and operational contexts. For example, installation standards may differ between cars, vans, heavy trucks, or specialized equipment. If installation is inconsistent, data quality may degrade—leading to false positives in alerting and undermining trust. Good suppliers help teams define acceptance tests and device verification steps before scaling.
It’s also common that integration is more complex than expected. Maintenance systems may have different data schemas, dispatch systems may not provide the same event cadence, and reporting may require mapping between identifiers. For that reason, ask for a clear integration plan that includes data ownership, mapping responsibilities, testing steps, and fallback procedures if an integration is unavailable.
Lastly, consider the human side of deployment: training, ongoing support, and documentation. A deployment can “technically go live” but still fail operationally if end users do not understand what the system is telling them. Effective suppliers include not only training sessions but also role-specific guidance: dispatchers need different operational instructions than maintenance planners or management teams.
6) An expert checklist: turning telematics data into measurable outcomes
Telematics value typically appears only after organizations operationalize data. Consider the following approach used by fleet operations analysts:
- Define decision goals: e.g., reduce unplanned downtime, improve route adherence, or strengthen safety documentation.
- Select metrics tied to those goals: align each metric with an action owner (dispatch lead, safety officer, maintenance planner).
- Set alert thresholds responsibly: avoid excessive alerts that lead to alert fatigue.
- Validate data quality: compare early weeks against known schedules or manual spot checks.
- Establish an operating rhythm: weekly reviews of exceptions, monthly maintenance pattern analysis, quarterly governance audits.
This is where Delfos Telematics can be very impactful: it provides consistent inputs, but the organization’s operational discipline determines the results.
To deepen this checklist into a more practical tool, consider the “metric-to-action linkage.” For every metric you track, define the following:
- Trigger: what measurement event causes concern (e.g., a geofence exit outside allowed window)?
- Owner: who receives the alert and who decides the next step?
- Response time: within how long should an investigation start?
- Expected resolution: what would “fixed” look like (e.g., correction to scheduling, coach driver, update maintenance plan)?
- Feedback loop: how will you record the outcome so future alerts improve (e.g., tuning thresholds, refining geofences)?
Many fleets also benefit from separating metrics into three categories:
- Leading indicators: measures that precede operational issues (e.g., rising idle time trends, increased harsh event counts).
- Lagging indicators: outcomes that confirm issues (e.g., breakdown frequency, late deliveries).
- Operational health indicators: system and process reliability (e.g., data completeness rates, alert delivery success).
This separation helps avoid the common mistake of focusing only on lagging outcomes. Telematics is often best at detecting early signals—so leaders should track leading indicators to ensure the organization can act before costs mount.
Finally, ensure that metrics are interpreted in context. For example, an increase in route deviation may be seasonal (e.g., roadworks) rather than behavioral. An expert operating model accounts for “normal exceptions” versus “unexpected exceptions” by using planned events or known disruptions.
7) Localization note: what changes for fleets “nearby” regional conditions
Fleet operations vary by region due to driving patterns, road density, typical delivery windows, and workforce practices. If your deployment is “nearby” a specific market or service area, you’ll likely need to adapt:
- Geofencing and route definitions: align with real delivery zones and customer site layouts.
- Operational hours and scheduling: ensure alerts match local work-time norms and shift patterns.
- Training language and approach: driver coaching should be communicated in a way that fits your local culture of feedback.
In many nearby contexts, a practical cultural nuance is that drivers respond better to transparent explanations of why monitoring is happening and how it supports safety and fairness. Over time, fleets often find that clarity improves adoption more than technical configuration alone.
Localization also includes operational constraints that affect data interpretation. Examples include:
- Weather and road conditions: harsh driving indicators or acceleration profiles may differ during snow, flooding, or heavy rainfall. Thresholds might require calibration or additional rules.
- Traffic patterns: stop-start behavior can be highly dependent on congestion patterns that vary by city or neighborhood. Without context, alerts may overrepresent “normal” activity.
- Shift organization: night shifts may require different alert policies than day shifts (different acceptable response times, different governance expectations).
- Local infrastructure: geofence accuracy depends on how consistent address matching and site boundaries are across the region.
To make localization effective, fleets often run a “local rules tuning” phase during the pilot. This can involve:
- adjusting geofence boundaries based on real site usage;
- tuning alert thresholds based on actual driving distribution;
- defining exceptions for known events like road closures, scheduled maintenance works, or local holidays;
- updating training materials and escalation scripts so staff interpret alerts consistently.
Localization also applies to governance. Data retention policies might be required to align with local legal expectations; user access permissions might need to reflect local organizational structure; and communication practices might need to match local labor norms. Even if the core telematics platform remains the same, governance and operational practices should be adapted to ensure legal compliance and smoother adoption.
In short, “nearby” regional operations are rarely identical. When fleets treat telematics as a configurable operational system rather than a one-size-fits-all tool, they typically realize better data accuracy, fewer false alarms, and stronger buy-in from end users.
8) Comparison table: how to evaluate Delfos Telematics deployment readiness
The following comparison table rephrases supplementary guidance into a clear decision framework. It is not a price list and does not include links.
| Evaluation area | What to check for Delfos Telematics | Good readiness sign |
|---|---|---|
| Operational use cases | Clear targets such as maintenance planning, route oversight, or safety-related review workflows | Each use case has an owner and a documented action plan |
| Governance and permissions | User roles for dispatch, maintenance, and management; data export controls | Access can be restricted by function and reviewed periodically |
| Data quality validation | Location signal behavior, reporting cadence, and expected accuracy for operational decisions | Early pilot matches schedules within an acceptable tolerance for your processes |
| Alert strategy | Thresholds, routing of notifications, and escalation steps | Alerts produce actions within defined time windows |
| Installation and onboarding | Device mounting standards, onboarding training, and configuration handover | Vehicles go live without repeated rework after initial rollout |
| Integration and reporting | Whether telematics data must connect to maintenance or fleet management systems | Reporting outputs match existing KPIs and decision meetings |
| Compliance posture | Policies on data retention, monitoring scope, and workforce communication | Documentation exists and stakeholders understand the “why” and “how” |
To make this readiness assessment more actionable, fleets can add a “readiness evidence” step. For each evaluation area, decide what proof you need. Examples:
- Operational use cases: sample runbooks and escalation scripts.
- Governance: role-matrix screenshots or policy documents.
- Data validation: pilot reports comparing telematics events with known schedules.
- Alert strategy: alert simulations and test cases.
- Installation: checklists used during device mounting and acceptance tests.
- Integration: mapping documents and integration test results.
- Compliance: retention schedule, access audit plan, and workforce communication records.
When these evidence items exist before full rollout, the project typically experiences fewer operational surprises later.
9) Step-by-step guide: implementing Delfos Telematics responsibly
Below is a practical, step-by-step guide for deploying telematics in a way that supports operational continuity and risk management. Adjust these steps to match your organization size and governance needs.
- Scope the fleet and assets: define which vehicles/assets will be tracked and why (e.g., service vans, delivery trucks, equipment).
- Confirm device and installation approach: align on hardware configuration, mounting standards, and acceptance checks before full rollout.
- Define metrics and decision workflows: set which dashboards and reports will be used in weekly and monthly operational meetings.
- Configure geofences and alerts with restraint: start with a limited number of high-value alerts and tune thresholds based on pilot results.
- Set user roles and data governance: decide who can view what data, who can export reports, and how frequently permissions are audited.
- Run a pilot: monitor performance, data consistency, and operational usefulness for a defined period.
- Conduct driver and staff communication: communicate purpose, monitoring scope, and how performance feedback will be handled.
- Review pilot outcomes and iterate: tune workflows, alerts, and reporting cadence; document lessons for rollout.
- Operationalize ongoing governance: schedule data quality checks, permission reviews, and quarterly KPI validation.
To expand this guide into a more “responsible deployment” playbook, consider adding a few operational safeguards around the edges of the process.
1) Scoping responsibly
During scope selection, decide whether telematics is intended for:
- operational optimization (routing and scheduling),
- maintenance decision support,
- safety and incident review,
- or compliance documentation.
Then align which signals will be collected and used for each purpose. If the organization intends to use driving-related indicators for coaching, define what type of coaching and how it will be evaluated (e.g., supportive coaching vs punitive actions). This helps build trust and reduces misunderstandings.
2) Installation acceptance and data verification
A strong pilot often includes an installation verification checklist. Examples include:
- device power/communication health checks;
- signal reporting cadence verification;
- geofence boundary tests at representative sites;
- baseline accuracy checks by comparing expected routes/times to recorded telematics events.
The goal is to ensure that the data quality is sufficient for operational decisions before scaling. Otherwise, you will spend later time trying to correct unreliable data rather than improving workflows.
3) Alert design discipline
Responsible alert design means you should avoid turning the system into a constant notification engine. Instead, define:
- which events are worth immediate action;
- which events are informational but should be reviewed in scheduled reviews;
- how to handle ambiguous events (e.g., partial geofence overlap);
- how to tune thresholds to reduce noise while maintaining sensitivity.
In mature operations, alerts are not just configured—they are treated like an operational product that must be iterated based on observed outcomes.
4) Pilot success criteria
Rather than treating a pilot as a “data collection period,” define success criteria that are measurable and time-bound. For example:
- data completeness reaches a target (e.g., near-real-time reporting for a majority of trips);
- alert accuracy is validated by comparing alert events to known operational realities;
- response time from alert to investigation matches operational targets;
- users adopt dashboards in defined workflows rather than only viewing data occasionally.
5) Workforce communication and governance
Driver communication should emphasize purpose, scope, and fairness. It can include:
- what data is collected (in broad terms);
- how it will be used for safety, coaching, or maintenance planning;
- who can access the data and how long it is retained;
- how to contest or clarify misunderstandings related to recorded events.
This communication layer is critical. Telemetry systems often fail adoption when staff feel the data is used without transparency or without a clear path to improvement.
6) Operationalize continuous improvement
After rollout, plan a recurring governance rhythm. The operating rhythm should include:
- weekly exception review (with documented outcomes);
- monthly data and threshold tuning review;
- quarterly KPI validation and policy review (including retention and access controls).
This makes telematics durable rather than temporary—ensuring it keeps producing value as operational conditions change.
10) Conditions and requirements to plan for before rollout
Teammates often underestimate the “non-technical” requirements in telematics deployments. Plan for these conditions to reduce friction:
- Stakeholder alignment: dispatch, maintenance, safety, and management should agree on what telematics will be used for.
- Clear escalation paths: if a route deviation or operational anomaly occurs, who investigates and by when?
- Training and adoption time: dashboards must match existing workflows; otherwise staff will revert to manual methods.
- Data retention and auditability: ensure policies cover how long data is stored and how it can be reviewed.
- Device lifecycle management: how devices are replaced or reconfigured when vehicles change hands.
These requirements matter because telematics systems affect daily work. The goal is not just to collect data, but to ensure the data reliably supports decisions without creating unnecessary operational burden.
Here are additional conditions fleets commonly face and should plan for early:
Data accuracy and operational tolerance
Every organization should define what accuracy is “good enough” for each use case. For example:
- Geofence breach alerts used for operational exceptions may require high accuracy at boundaries.
- Monthly utilization metrics may tolerate slightly lower precision if trends remain stable.
- Safety incident review might require consistent timestamping more than perfect location precision.
By defining tolerances upfront, you reduce the risk of unrealistic expectations and later frustration.
Identity and assignment workflows
If telematics is used in contexts where vehicle-to-driver assignment matters, plan for how assignments are captured. Common challenges include:
- drivers swapping vehicles mid-shift;
- late updates to driver assignments in operational systems;
- exceptions like relief drivers or contractors.
When identity mapping is inconsistent, performance analytics may become less reliable and perceived as unfair. Responsible governance includes defining how identity and responsibility are managed.
Exception taxonomy
Not all anomalies are equal. Fleets benefit from defining categories such as:
- expected deviations (e.g., customer site differences, temporary roadworks);
- investigation-required deviations (e.g., unexplained route changes);
- critical incidents (e.g., safety-related events);
- device/system issues (e.g., communication dropouts).
This taxonomy helps dispatchers and managers know what to do quickly and prevents all alerts from being treated as urgent.
Support and escalation during early rollout
The first weeks after rollout often require extra support. Plan for:
- a process to report device issues and data gaps;
- clear escalation to supplier support for hardware or configuration errors;
- temporary manual verification steps until confidence is achieved.
Budgeting for the operational side
Telematics projects can create operational workload even if the software is “automated.” Budget time for:
- alert review staffing;
- maintenance workflow validation;
- driver coaching sessions or documentation;
- reporting for management and governance.
Otherwise, the project may be seen as an additional administrative burden rather than an efficiency enabler.
11) Industry context: what reputable research suggests about telematics outcomes
When fleets adopt telematics, the expected benefits commonly fall under operational efficiency, safety management, and maintenance optimization. While outcomes differ by organization, large-scale research and industry reporting generally supports the premise that real operational gains depend on implementation quality and how systems are used.
For broader context, consider these reliable sources:
- EU Agency for Network and Information Security (ENISA) reports and guidance related to managing risk in connected systems (useful for governance framing of connected vehicle data). Source: ENISA publications.
- UK Department for Transport (DfT) and related transportation research often discuss how data can support transport efficiency and safety outcomes. Source: DfT research and strategy documents.
- International standards bodies (e.g., ISO) publish guidance that can inform governance practices for management systems and information security controls.
Note: Specific numeric claims about savings or risk reduction should be tied to your environment and validated during pilot testing. Avoiding unverified figures is essential for objective evaluation.
To make the research context more operational, it helps to interpret what “good telematics outcomes” usually require. Across many studies and industry best practices, recurring themes include:
- Data reliability: outcomes are weaker when data quality is inconsistent or alert thresholds are not calibrated.
- Operational alignment: benefits grow when dispatch, maintenance, and safety teams coordinate through shared workflows.
- Change management: adoption improves when staff understand purpose, fairness, and how feedback is handled.
- Governance and security: connected data introduces risk that must be managed via access control, retention policies, and monitoring.
- Continuous improvement: systems that are iteratively tuned over time outperform systems that remain static after go-live.
Additionally, research and public guidance often emphasizes that telematics is most effective when it supports decision-making rather than producing “data for data’s sake.” In that sense, the operational loop—measure, interpret, act, review—is a consistent message across industry guidance.
From a practical governance standpoint, you can interpret telematics success as achieving a defensible operational model: decisions are supported by recorded evidence, exceptions are managed consistently, and the organization can explain how and why actions were taken. This becomes particularly important when incidents occur and you must reconstruct what happened using reliable event timelines.
In procurement and vendor evaluation discussions, you can use this context as a lens: ask how the platform supports governance, how it enables calibration and tuning, and how it supports training and ongoing operational workflows.
12) Frequently asked questions (FAQs)
Q1: What exactly is Delfos Telematics used for in fleet operations?
It is typically used to support fleet visibility and operational oversight by collecting vehicle and asset signals, enabling tracking and analysis that can inform dispatch decisions, maintenance planning, and structured review of driving and operational patterns. The exact scope depends on your configuration and enabled modules.
Q2: How do we evaluate Delfos Telematics pricing fairly?
Ask for a written quotation that breaks down per-vehicle or per-asset platform fees, device or configuration costs, installation/onboarding charges, support terms, and any additional modules. Compare options using the same vehicle count, contract term, and required functionality.
Q3: Will telematics interfere with day-to-day driver work?
When implemented well, telematics typically runs in the background. The main “driver impact” is often the process around coaching, performance feedback, or investigations triggered by alerts. Clear communication, fair policies, and calibrated alert thresholds help minimize disruption.
To reduce friction further, some fleets define a “no-surprise” policy for performance discussions: drivers receive periodic summaries through agreed channels rather than only being contacted after an exceptional event. This can support a more constructive environment while maintaining accountability.
Q4: Can telematics data be used for compliance and reporting?
Yes, when governance is defined. Many fleets use telematics records for internal audits, safety reviews, and operational accountability. Your legal and policy framework should define retention periods, access permissions, and permissible uses of workforce-related data.
Responsible compliance usage also means establishing audit procedures. For example, when an incident occurs, document who accessed the data, which datasets were used, what thresholds or rules triggered any alerts, and how conclusions were formed. This creates defensible, transparent reporting.
Q5: What should we do before expanding from a pilot?
Review data quality, user adoption, and operational response time to alerts. Confirm that dashboards reflect real decision needs and that staff can interpret the outputs correctly. Only then should you scale up the number of vehicles/assets and enable additional modules.
Expansion readiness also includes evaluating whether alert volumes remain manageable. If expansion would multiply alerts beyond what the organization can process, you must tune thresholds and workflows first.
Q6: What conditions are required for successful deployment near a local operating area (“nearby”)?
Adapt geofencing and routes to match local delivery zones, ensure training language and feedback practices align with local culture, and tune alert thresholds to reflect local driving and traffic patterns. These adjustments improve accuracy and reduce false positives.
Additionally, ensure you have a plan for local exceptions—like roadworks or recurring access constraints at customer sites. Without a defined exception process, pilots may show many “false alerts” that can be avoided through localization tuning.
Q7: How can we ensure data governance and access control?
Define user roles (dispatch, maintenance, management), restrict exports where needed, document permission review cadence, and retain data according to your internal policies and applicable regulations. A governance owner—often within operations or compliance—should be assigned.
To strengthen governance, consider implementing regular access reviews and documenting changes. It is also useful to log administrative actions in the platform (e.g., changes to geofences, threshold modifications, and user role changes) so governance remains auditable.
13) Practical recommendations: making the very of Delfos Telematics
If you want Delfos Telematics to deliver consistent value, focus on the operational loop: measure, interpret, act, and review. In many deployments, teams succeed by:
- starting with a small number of high-impact workflows (for example, maintenance triggers or route deviation review),
- ensuring alert handling is staffed and time-bound,
- training end users on “what the data means” rather than only “how to view it,”
- maintaining documentation so that your processes remain stable even when staff changes occur.
Done this way, telematics becomes a reliable operational layer instead of a fragmented analytics tool.
Here are additional practical recommendations that often separate successful fleets from “pilot-only” deployments:
1) Treat alerts like a product with a lifecycle
Alerts should not be set and forgotten. A mature approach includes:
- measuring alert precision (how many alerts correspond to real issues);
- measuring response outcomes (what actions were taken and whether they resolved the issue);
- iterating thresholds based on observed conditions and operational feedback.
This reduces alert fatigue and builds confidence in the system.
2) Build a maintenance planning logic that uses telematics appropriately
Telematics can support maintenance decisions by identifying usage patterns and operational conditions. However, the key is to avoid “over-automation.” A good model is:
- use telematics to suggest or trigger reviews;
- validate triggers with maintenance inspection outcomes;
- update maintenance schedules based on evidence, not solely on telematics readings.
This approach helps prevent unnecessary maintenance work while still catching early wear.
3) Standardize operating procedures across teams
If multiple regions or depots use the system, standardization helps. For example:
- use consistent definitions for what counts as “late,” “idle,” or “deviation”;
- use consistent templates for investigation notes;
- run the same weekly review cadence and document outcomes in a shared format.
Standardization improves comparability of KPIs and makes training more efficient.
4) Use telematics to improve scheduling, not only to monitor problems
Many fleets initially use telematics as a monitoring system. Over time, they can expand into planning improvements. Examples include:
- adjusting route plans based on typical travel times and observed route adherence;
- re-forecasting resource allocation based on utilization patterns;
- reducing idle time by modifying dispatch windows and assignment logic.
This shift from reactive monitoring to proactive planning often delivers larger ROI.
5) Ensure your dashboards reflect actual decision meetings
A common failure point is building dashboards that look good but are not used. To prevent this:
- align each dashboard with a specific meeting (weekly exceptions, monthly maintenance review, quarterly governance audit);
- include only the KPIs that are discussed and acted on;
- ensure dashboards allow drill-down from KPI to event timeline when investigating issues.
6) Make documentation a first-class deliverable
Even with the best system, staff turnover can disrupt processes. Documentation should include:
- how to interpret key alerts and metrics;
- who to contact when specific alerts occur;
- how thresholds and geofences were configured (and why);
- what “normal exceptions” are for your operating environment.
When documentation exists, the operational system remains resilient.
7) Create a feedback loop with drivers and supervisors
To maintain adoption and fairness, you can implement a simple feedback loop. For example:
- drivers can report situations where an alert might have been caused by exceptional circumstances;
- supervisors can provide evidence to refine geofences or thresholds;
- the telematics governance owner can log changes and track whether tuning reduces false positives.
This makes telematics a collaborative operational improvement tool rather than a surveillance mechanism.
8) Plan for “data governance maturity” over time
Governance can start simple and mature. Early-stage governance might focus on access permissions and retention. Later-stage governance can expand into:
- advanced auditing and traceability for incidents;
- regular permission reviews and role re-certification;
- compliance reporting automation or evidence generation.
This staged approach helps fleets avoid overwhelming governance processes before operational value is demonstrated.
Collectively, these recommendations reinforce the same principle: telematics delivers best results when it becomes part of the organization’s operating system—supported by clear ownership, documented workflows, and a continuous improvement rhythm.
14) Conclusion
Delfos Telematics can be a strong foundation for fleet visibility and operational control when organizations treat it as a system of governance and workflows—not merely a data-collection platform. By planning pricing evaluation carefully, aligning supplier responsibilities, validating data through a pilot, and operationalizing decision routines, fleets can convert telematics signals into measurable improvements while maintaining responsible oversight.
The most successful deployments share a common pattern: they focus on actionable use cases, calibrate alerts to reduce noise, define escalation paths, and build an operating cadence that turns information into continuous improvement. When fleets combine telematics technology with disciplined operations and transparent workforce communication, the platform becomes more than a dashboard—it becomes a practical mechanism for managing safety, reducing downtime, and improving service reliability over time.
-
1

Maximizing Your Purchase: Ram 1500 Deals and Towing Capacity
-
2
Maximizing Benefits of Solar Panels: Costs and Energy Efficiency
-
3
Affordable Stair Lifts for Seniors: A Comprehensive Guide
-
4
The Ultimate Guide to Lab-Grown Diamonds: Ethical & Cost-Effective Choices
-
5
The Ultimate Guide to Weight Loss Injections, Metabolism, and Appetite Suppression